In this article
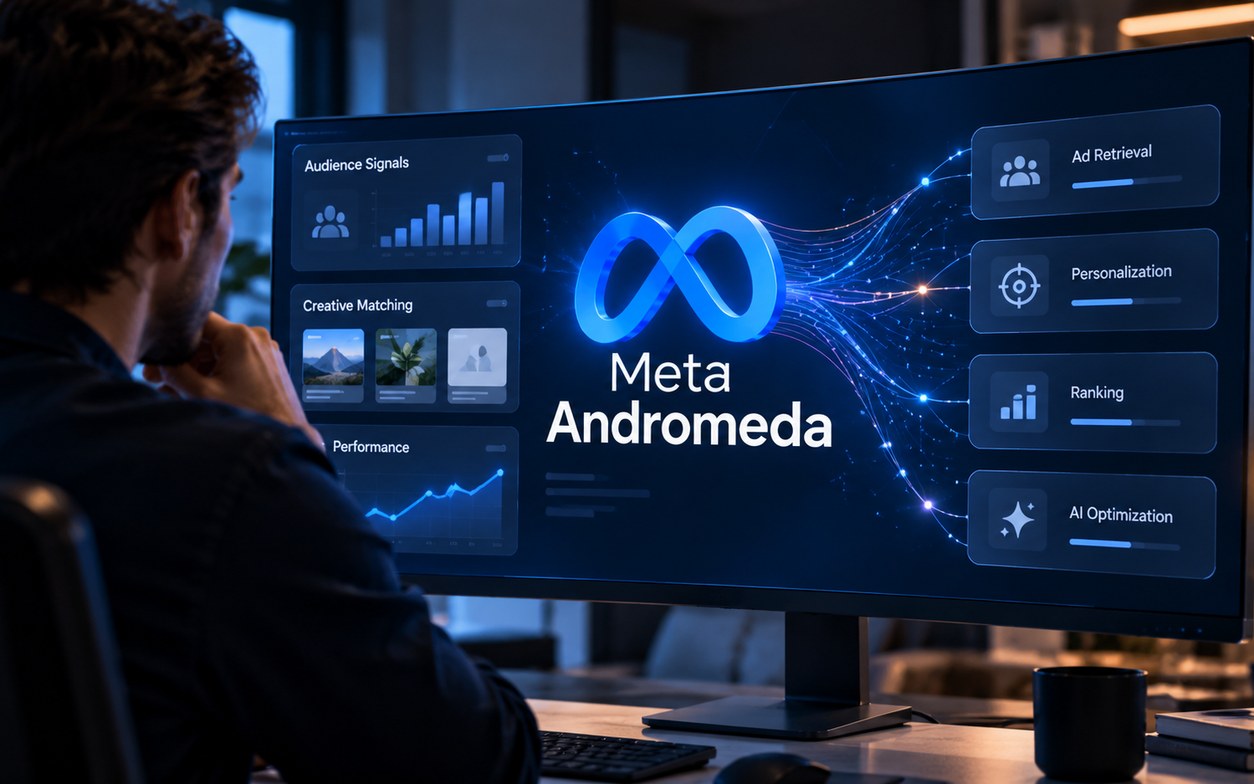
In recent years Meta has moved a growing share of advertising decisions to artificial intelligence systems. Targeting, ad selection, ranking, recommendation and the interpretation of behavior no longer depend on a single algorithm, but on several models working together.
Andromeda is the one that has received the most attention, but looking at it alone risks missing the point. In the system Meta describes, Lattice, GEM and Sequence Learning also come into play, each with a different role in the delivery and optimization process.
For anyone running campaigns, though, knowing the names of the models only goes so far. The more useful question is a different one: if Meta automates more and more decisions, which levers really stay under our control?
The answer depends above all on the quality of the inputs we give the platform.
Andromeda, Lattice, GEM and Sequence Learning: who does what
The four models step in at different moments of the same process.
Andromeda works on the initial selection of ads. Lattice evaluates and transfers learning across objectives and surfaces. GEM refines the recommendation for the individual user. Sequence Learning adds the time dimension and tries to interpret behavior as a sequence rather than a series of independent events.
Andromeda: which ads make the shortlist
Andromeda operates in the ads retrieval phase.
When Meta has to decide which ad to show a person, the system starts from an enormous number of possible ads. Andromeda progressively narrows this set and identifies the ones most likely to be relevant for that specific user.
To do so it uses different signals: interaction history, previous engagement and conversions, the semantics of text and visuals, geographic and time context, device and browsing session. Ads and users are represented numerically and compared to estimate their affinity.
The technically interesting part is the scale. Instead of analyzing every ad in sequence, Andromeda uses a hierarchical structure that groups ads and progressively narrows the field. This lets Meta handle much larger creative pools without a proportional increase in computing cost.
Lattice: how Meta transfers learning
Lattice steps in at the ranking phase.
Its logic is to reduce reliance on many separate models and use an architecture that can learn more broadly across different objectives, placements and surfaces.
What the system learns in one context can therefore contribute to predictions in another. A pattern observed on Reels, for example, can also become useful in how conversion-oriented campaigns are evaluated on other surfaces.
For the advertiser the consequence is fairly clear: the more we artificially fragment data and structures, the harder it becomes to generate consistent volumes of signals.
GEM: which ad is most relevant for that user
GEM is a recommendation model. Its job is to estimate which ad, among those already shortlisted by the system, is most likely to produce a positive response from a specific user.
It does not look only at aggregate performance. It looks for relationships between people, ads, products, context and behavior, also using very granular signals. From this comes an important principle for the creative side: variants have to be different enough to produce information, but consistent enough for the system to recognize patterns.
Sequence Learning: not just what to show, but when
Sequence Learning adds an element that was less central in earlier models: time.
Instead of observing only a click, a visit or a conversion, it tries to interpret the succession of actions. The aim is to understand where the user is in the journey and what the next most relevant step might be.
This makes tracking quality particularly important. If a sequence is incomplete, duplicated or out of order, the model also receives a worse representation of real behavior.
How the four models divide the work
Andromeda
Which ads deserve to be evaluated?
Selects the initial pool of relevant ads.
Lattice
How should they be evaluated?
Transfers learning across objectives, placements and surfaces.
GEM
Which ad is most relevant for this user?
Refines the recommendation using relationships and behavioral signals.
Sequence Learning
At what moment is it most useful to show it?
Interprets the time sequence of actions and the context of the journey.
What really changes in managing Meta Ads campaigns
The most important consequence is not that we have to learn four new names, but that the system tends to work better when it receives consistent signals, enough volume and continuity over time. This is why consolidation, stability and reduced fragmentation keep coming up.
Less fragmentation, more usable signals
Multiplying campaigns, ad sets and segmentations can look like a way to gain more control. But every isolated structure collects less data.
Budgets that are too fragmented, audiences that are too small and parallel campaigns all reduce the volume of signals available for learning. The same principle returns in how Lattice works, which benefits from being able to learn more broadly.
Consolidating does not mean putting everything in the same campaign. It means avoiding divisions that exist only because we are used to building accounts that way.
Stability does not mean leaving everything on
The other extreme is wrong too.
Giving the system time does not mean ignoring a campaign that is clearly going in the wrong direction. It means avoiding constant changes when there is not yet enough evidence to justify them.
Consolidating means intervening less, and doing it when it is really needed.
Opportunity Score: an indicator, not a business KPI
Opportunity Score measures, from 0 to 100, how closely campaigns, ad sets and ads align with Meta’s recommendations. It does not measure performance directly: a higher score signals closer adherence to the best practices the platform suggests, but it does not guarantee a better CPA, more sales or greater profitability.
The same goes for automatic recommendations. They can be useful, but they should not become orders to apply regardless of context. If a change improves the score but compromises brand identity, creative control or strategy, the score cannot be the only decision criterion.
From fragmented management to a system that learns
Weak approach
- Many isolated micro-campaigns
- Fragmented budget
- Constant changes
- Optimizing a single lever
- Opportunity Score as the goal
Approach better suited to the new ecosystem
- More consolidated structures
- Enough volume to generate signals
- Stability and justified interventions
- Reading the system as a whole
- Opportunity Score as an indicator
Creative becomes a system of signals
One of the most interesting shifts is the move from Unique Selling Proposition to Multiple Selling Proposition.
The idea is not that brand positioning no longer matters. It is the opposite.
You need a coherent core strong enough to be translated into several motivations, messages and variants without losing identity.
A product can be told through functional benefit, convenience, design, performance, social proof or value for money. They are different propositions, but they can belong to the same system.
A single promise vs a system of messages
Unique Selling Proposition
- one main promise
- one dominant message
- one central creative distributed at scale
Multiple Selling Proposition
- several purchase motivations
- different but coherent angles
- variants that produce different signals for the system
Variety yes, chaos no
This does not mean producing dozens of completely unrelated assets.
Variants, formats and creatives have to be readable enough for the model to understand what is changing and which patterns are emerging.
The distinction matters: creative diversification does not mean creative randomness.
Changing message, format, target, CTA and campaign structure all at once produces movement, but not necessarily useful learning.
This theme connects directly to our creative testing framework and to the question of how many creatives you really need on Meta Ads: the number alone says very little if the assets do not have a precise function within the test.
Test by hypothesis, do not produce random variants
A more useful process starts from a question. The sequence is simple: formulate a hypothesis, create micro-variants, keep the test context stable and use the results to decide what to carry forward.
A creative cycle that serves the algorithm better
- 1
Formulate a hypothesis
Define what you want to find out before producing new variants.
- 2
Create controlled variants
Change the hook, visual, CTA, format or tone without turning every asset into a completely different test.
- 3
Keep the test context stable
Avoid changing structure, objective and creative at the same time.
- 4
Iterate on the signals collected
Keep what generates useful indications and use the results to guide the next production.
Without clean data, AI does not solve the problem
The more sophisticated the models become, the easier it is to forget something very simple: they work on the data they receive.
If the signal is incomplete, duplicated, delayed or inconsistent, the sophistication of the model does not remove the problem.
The quality of learning also depends on tracking, Event Match Quality, Conversions API, deduplication and event latency.
The problem is not just collecting events
Having the Pixel and CAPI active is not enough.
You need to check that the same event is not counted twice, that browser and server use consistent identifiers, that events arrive in the right order, that the important stages of the funnel have no gaps and that data arrives with reasonable latency.
For Sequence Learning this is particularly relevant. If the model has to interpret a sequence like ViewContent → AddToCart → Checkout → Purchase, losing one of these steps changes the meaning of the sequence itself.
Four checks not to ignore
- Event Match Quality
- ≥ 8
- Measures how effectively Meta manages to link conversion events to user profiles.
- Indicative reference for the main events
- CAPI coverage
- ≥ 75%
- Measures the coverage of server-side events compared with those recorded by the Pixel.
- Indicative reference
- Deduplication
- Consistent IDs
- Pixel and CAPI must represent the same action without creating duplicate conversions.
- Operational goal
- Latency
- Regular checks
- Events sent too late or out of sequence make behavior harder to read.
- Periodic verification
A dirty signal produces dirty learning
A duplicated Purchase is not simply a reporting problem.
A missing AddToCart is not just one line fewer in Events Manager.
They are pieces of information that enter the systems used to interpret behavior and optimize delivery.
That is why tracking and media buying can no longer be treated as two completely separate disciplines.
Before looking for a problem in the algorithm
- Are the main events tracked correctly?
- Are Pixel and CAPI deduplicated?
- Do the funnel sequences make sense?
- Do signals arrive with acceptable latency?
- Are the campaigns collecting enough volume?
- Have recent changes been documented?
More automation requires more strategic control
The last risk is thinking that a smarter system makes human interpretation less important.
The problem of algorithmic confirmation bias arises when we automatically consider correct whatever the platform suggests, simply because it comes from a model or a recommendation.
But a metric can be perfectly optimized and still be of little use to the business.
A low CPA does not guarantee customer quality. A high Opportunity Score does not guarantee profitability. A rise in conversions does not automatically prove that a single campaign change caused it.
Correlation is not causation
The more complex the system becomes, the harder it is to isolate a direct relationship between a change and a result.
An observed variation may depend on ranking, but also on seasonality, the market, brand awareness, other marketing activity or combinations of signals the platform is interpreting at the same time.
That is why attribution should be treated as an estimate, not as an absolute certainty.
The same goes for the so-called black box effect. If thousands of signals are weighted dynamically, we cannot always explain precisely why a given combination produced a better result.
What Meta can optimize and what stays with the advertiser
Meta can optimize
- Delivery
- Ranking
- Recommendation
- Allocation
- Prediction
The advertiser has to decide
- The economic objective
- Positioning
- Which messages represent the brand
- How much risk to accept
- How to interpret the result
Do not chase every shiny object
A new feature, an emerging placement or a new automation can be interesting.
But if tracking, structure and creative are weak, adding another tool is unlikely to solve the problem.
Constantly chasing novelty without consolidating data, creative and objectives produces weak inputs for the whole system.
Before changing anything else
- Tracking
- Structure
- Signal volume
- Stability
- Creative variety
- Test consistency
Meta will probably keep automating a growing share of delivery. That does not make the advertiser’s work useless. It changes where it is applied.
Knowing Andromeda, Lattice, GEM and Sequence Learning helps you understand what is happening behind Ads Manager. But the advantage does not come from trying to "beat" the algorithm or from reacting to every new update.
It comes from the ability to build better conditions for the system to learn, while keeping enough control to tell when a recommendation makes sense for the business and when it does not.
The more Meta automates delivery, the more the decisions made before delivery matter.
It is also the principle behind Paid Social management that does not stop at intervening on campaigns, but works on structure, creative, signals and allocation.
FAQ
What is the difference between Andromeda, Lattice and GEM?
Andromeda works mainly on retrieval and selects which ads enter the pool to be evaluated. Lattice steps in at ranking and transfers learning across objectives and surfaces. GEM refines the recommendation by trying to work out which ad is most relevant for a specific user. Sequence Learning adds the time dimension of behavior.
Does Andromeda require more creatives?
Not simply more creatives. Greater variety can give the system more material to learn from, but the assets have to be coherent and structured. Many random creatives can add noise instead of improving learning.
Does a high Opportunity Score guarantee better performance?
No. Opportunity Score measures alignment with Meta’s recommendations and best practices. It does not measure performance directly and does not guarantee better economic results.